Establish the data platform for your AI GCC.
Establish a shared data platform for your AI GCC, with clear ownership, access controls and reusable datasets for multiple teams.
How we help
Make trusted data available across your AI GCC.
For centers where teams need a shared data foundation and clear ownership. We help organize the platform, access rules and data responsibilities that allow several AI workloads to use reliable inputs.
What the work covers
- A data platform plan mapping sources, owners, consumers and access requirements.
- Shared standards for pipelines, quality checks, documentation and reusable datasets.
- A responsibility model for enterprise data owners and the GCC engineers who maintain the platform.
What we need from you
A source-system inventory, data owners, existing platform standards and approval for the data your India team will access.
Agree before we start
Confirm which sources and platform components are included, who corrects source data and who supports failures. Individual pipeline or application implementations need a defined delivery scope.
From sources to AI workloads through governed data products.
The data product layer is the point. It is what lets the third AI use case cost less than the first.
Sources
Operational systems, documents, events, third-party feeds.
Data platform
Ingestion, batch and streaming, storage, transformation, quality.
Governed data products
Reusable, owned, documented datasets with lineage and access control.
AI workloads
Features, retrieval indexes, training sets, evaluation sets, agents.
- 01
Sources
Operational systems, documents, events, third-party feeds.
Data platform
Ingestion, batch and streaming, storage, transformation, quality.
02- 03
Governed data products
Reusable, owned, documented datasets with lineage and access control.
AI workloads
Features, retrieval indexes, training sets, evaluation sets, agents.
04
What the data foundation includes.
Data platform architecture
Lakehouse or warehouse design, ingestion patterns, orchestration, transformation standards and the platform team model the GCC will run it with.
Batch and streaming
Reliable batch pipelines and streaming where latency matters, with schema management, replay and monitoring designed in.
AI-ready data products
Owned, documented, versioned datasets built for reuse across ML, GenAI and analytics rather than rebuilt per use case.
RAG and unstructured data foundation
Document ingestion, parsing, chunking, metadata, embeddings and refresh pipelines that keep retrieval systems current and permission-aware.
Evaluation datasets
Curated, versioned evaluation sets for models, prompts, retrieval and agents, treated as first-class data products with owners.
Feature and vector infrastructure
Feature stores where they earn their keep, vector stores sized to the retrieval workload, and the serving paths that connect them to production.
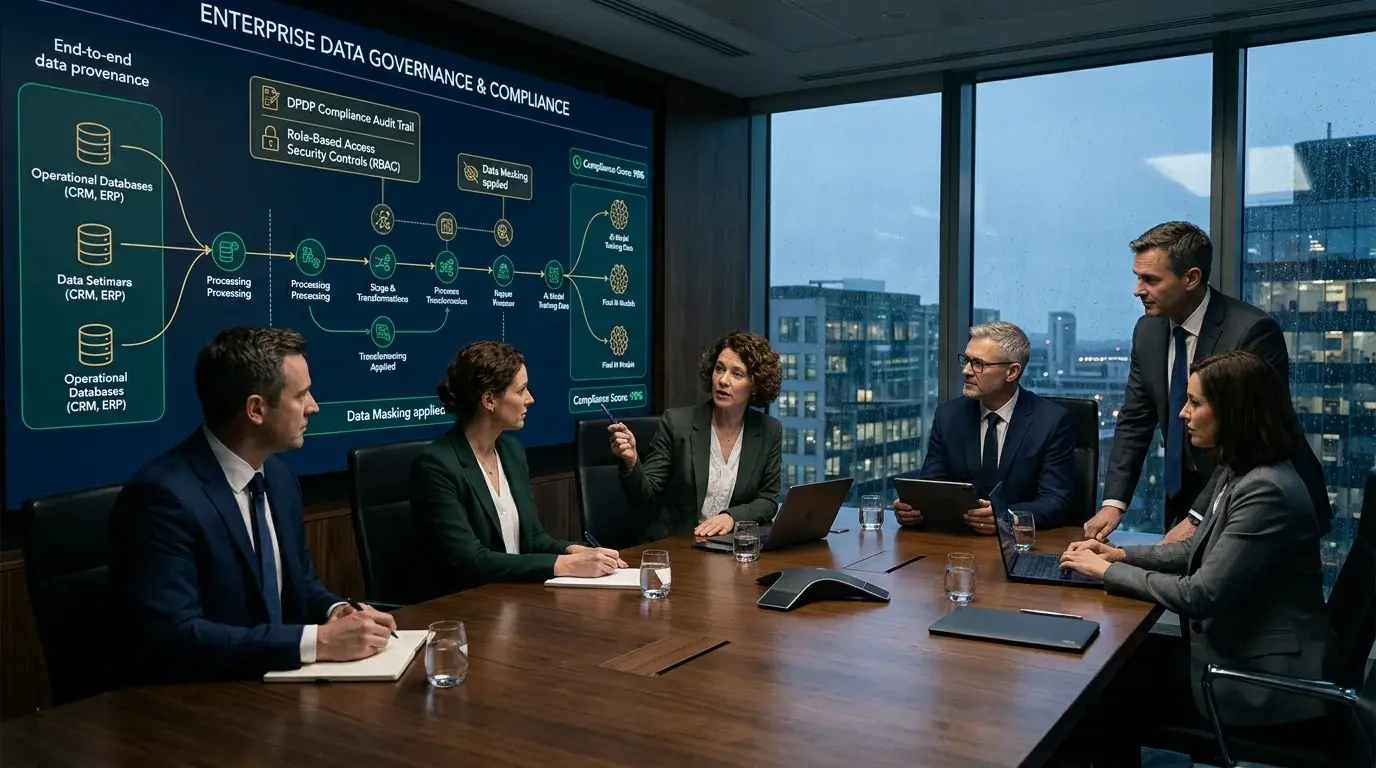
Governance and lineage
Classification, access control that follows the source, lineage from source to model, and the records privacy and audit teams ask for.
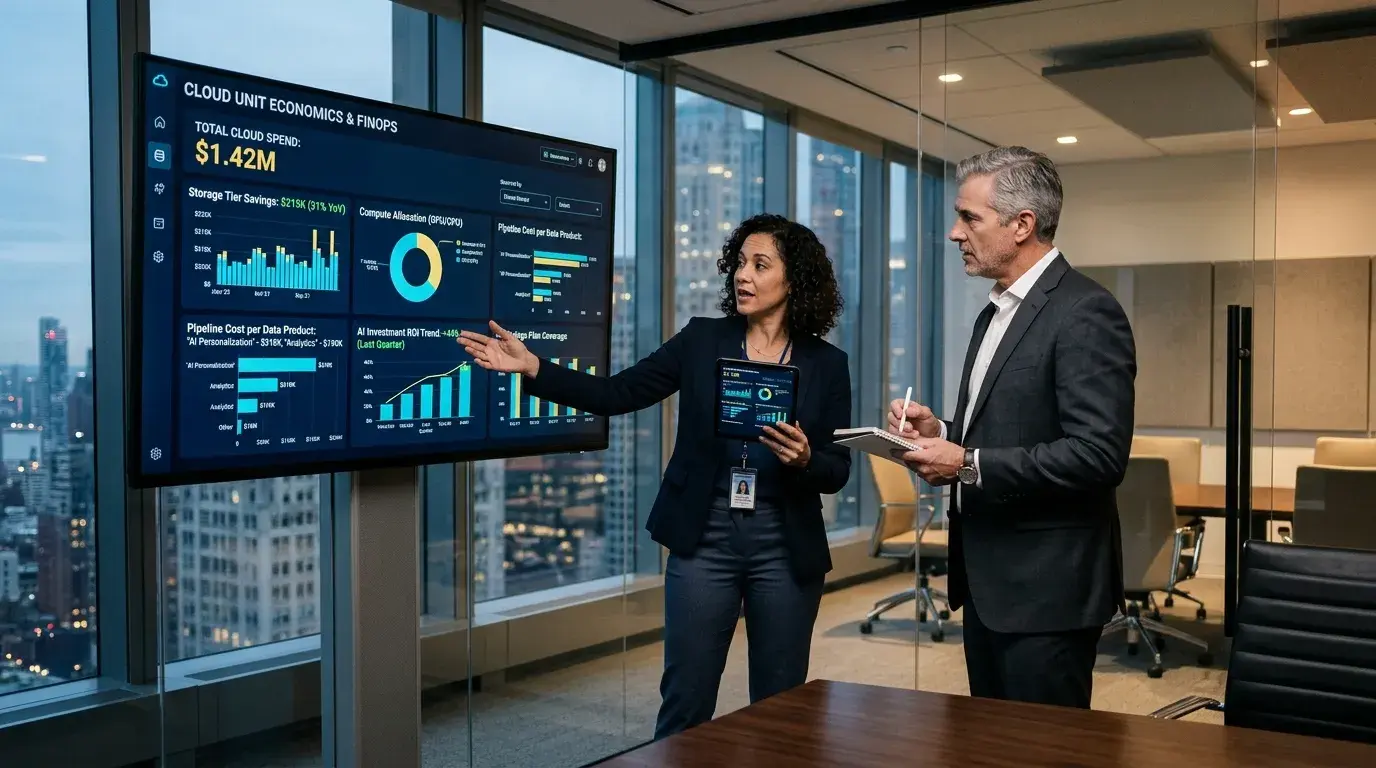
Data FinOps
Storage tiers, compute allocation, pipeline cost per product and the reviews that keep the platform bill tied to the value it produces.
Every data decision is made for the AI workloads that depend on it.
Data, models, agents, evaluation, MLOps and governance are one system in an AI GCC. Data engineering is scoped against all of them.
ML
Features, training sets and lineage that make a model reproducible and explainable.
GENAI
Parsed, chunked, permission-aware documents with refresh pipelines behind every retrieval system.
AGENTS
Clean, typed access to the systems agents act on, with the audit trail their actions require.
EVALUATION
Versioned evaluation datasets owned like production data, so quality is measured against the same truth every release.
MLOPS
Data validation and contracts wired into CI/CD, so a pipeline change cannot silently break a model.
GOVERNANCE
Classification, residency and lineage that give AI governance the evidence it needs without a separate project.
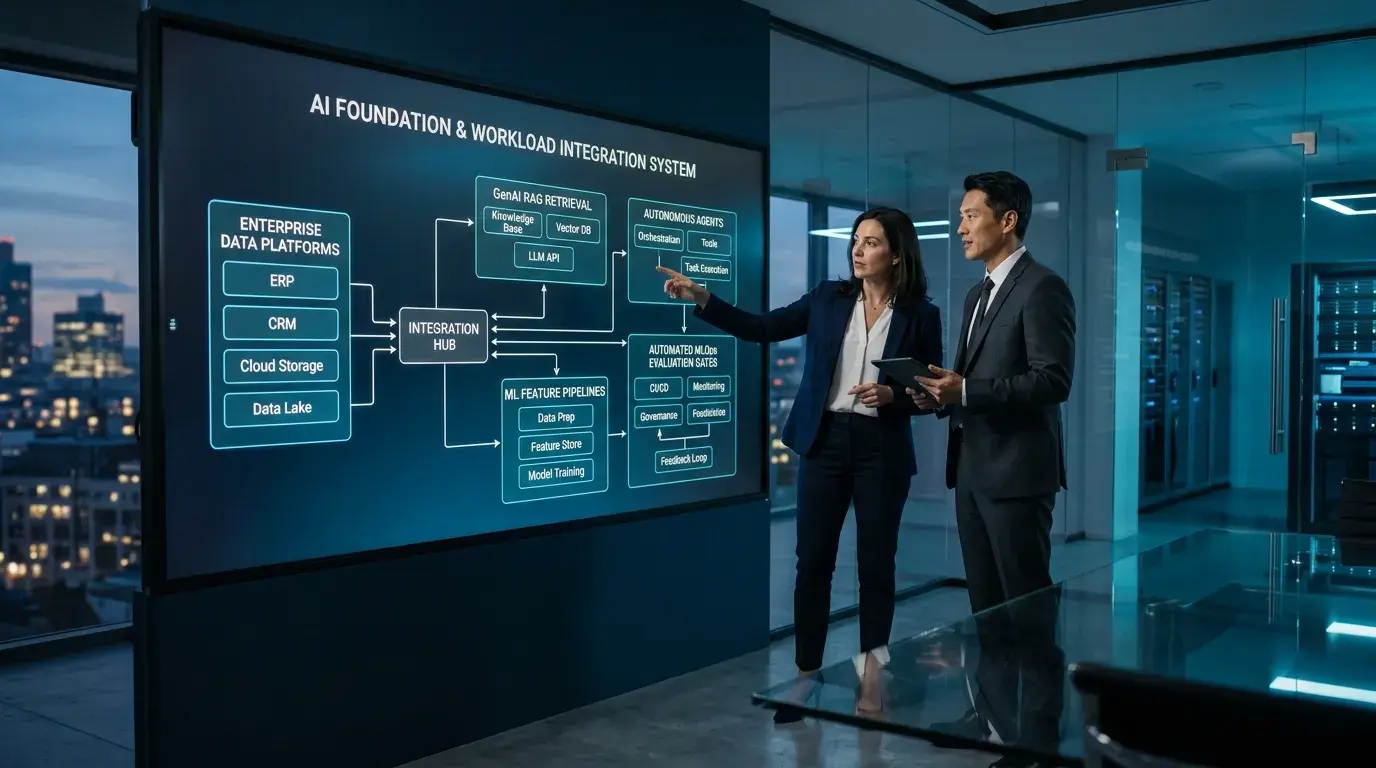
AI delivery depends on reliable data and a named owner for its quality and availability.
Production consumers of the foundation are described under Generative & Agentic AI and MLOps, LLMOps & AgentOps.
What the data foundation is measured on.
Questions about data engineering for AI GCCs.
How is data engineering for an AI GCC different from a data warehouse program?
The consumers are models, retrieval systems, evaluation pipelines and agents as well as dashboards. That adds unstructured data, vector infrastructure, evaluation sets and lineage into training and inference, and it changes what 'done' means for a pipeline.
Do we need a feature store or a vector store?
Only when a workload justifies it. Feature stores pay off with many models sharing features under latency constraints. Vector stores are required for retrieval at scale. Both are decisions made per portfolio, not defaults.
How do you handle data quality?
With contracts at the boundary of each data product, automated checks that run in the pipeline, ownership for every product and monitoring that alerts the owner, not a shared inbox.
How does data governance work with India's data protection law?
Classification, residency mapping, access control and lineage are designed to support the client's obligations, including under the Digital Personal Data Protection Act, 2023 and applicable rules. NeoIntelli provides technology and governance support; legal interpretation sits with the client's advisers.
Which cloud and tooling do you use?
The client's cloud and, where sensible, the client's existing tooling. The platform design is driven by workload, skills and governance, not by a preferred vendor list.
Assess the data foundation before the next model.
Share the sources, the AI use cases queued behind them and where pipelines break today. We will map the platform, the data products and the governance the GCC needs to reuse them.
Terms explained for business leaders
- AI operations and quality control
- MLOps, LLMOps and AgentOps cover how models, language-model systems and agents are tested, monitored, updated and kept within agreed quality, risk and cost limits.
- NeoHireX
- NeoIntelli's AI screening and interview platform supports recruitment. Your hiring team makes the final hiring decision.
- Embedded AI engineers
- Forward-deployed engineers work directly with your product and business teams to integrate AI into actual workflows.
- Employment and ownership
- An employer of record (EOR) employs people through a local entity. Build-Operate-Transfer (BOT) includes an agreed handover path. Captive means your own subsidiary. Confirm the actual employment, IP and transfer arrangements in the agreement.
- Compensation and payroll
- CTC means total annual compensation cost to the employer. BGV means background verification. PF, ESI, PT and LWF refer to Indian retirement contributions, employee insurance, professional tax and labor welfare arrangements; applicability varies.
- Export and tax planning
- STPI refers to Software Technology Parks of India and SEZ to a special economic zone. GST is India's goods and services tax; FEMA governs foreign exchange. Eligibility for incentives or transfer-pricing safe harbor treatment requires current advice on the actual transaction and entity.